

Vector Search with Matryoshka Embeddings
On this page
Matryoshka embeddings are trained to preserve useful information in the earlier dimensions of a vector.
A Matryoshka-capable model generates a single full embedding, which can then be truncated to different prefix lengths for vector search.
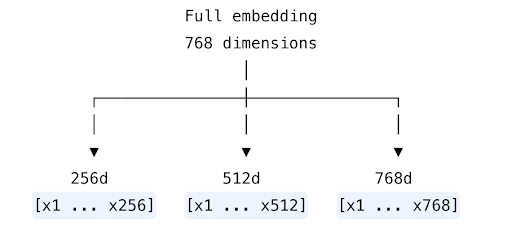
Common use cases include:
-
Speed-sensitive search: Use a shorter prefix for high query volumes or large collections, where reduced vector processing matters more than exact ranking.
-
Accuracy-sensitive search: Use more dimensions when ranking accuracy is more important.
-
Multi-stage retrieval: Use a shorter prefix for initial candidate retrieval and a larger representation for a subsequent ranking stage.
Example Implementation
The following example demonstrates how to generate a Matryoshka embedding, truncate it to different prefix lengths, and compare vector search results at each dimensionality.
Note: This section shows key code excerpts from the example.
-
Nomic Embed v1.
5 model setup -
Sample Pride and Prejudice dataset
-
Embedding generation
-
SingleStore database setup
-
Vector search at multiple dimensionalities
-
Search-result comparison
Generate the Embedding
Generate one 768-dimensional embedding for a document, then truncate it to 64, 128, 256, 512, and 768 dimensions:
import numpy as npfrom sentence_transformers import SentenceTransformermodel = SentenceTransformer("nomic-ai/nomic-embed-text-v1.5",trust_remote_code=True)DIMENSIONS = [64, 128, 256, 512, 768]def generate_document_embedding(text, dimensions):full_embedding = model.encode(f"search_document: {text}",convert_to_numpy=True,normalize_embeddings=False)result = {}for dim in dimensions:truncated = full_embedding[:dim]normalized = truncated / np.linalg.norm(truncated)result[dim] = normalized.tolist()return result
This produces five vectors from the same original embedding.
Note: This example uses L2 normalization after truncation for simplicity.
The same prefix-generation process is applied to query embeddings, using the search_: task prefix.
def generate_query_embedding(text, dimensions):full_embedding = model.encode(f"search_query: {text}",convert_to_numpy=True,normalize_embeddings=False)result = {}for dim in dimensions:truncated = full_embedding[:dim]normalized = truncated / np.linalg.norm(truncated)result[dim] = normalized.tolist()return result
Store Embeddings at Different Dimensionalities
Create a table called documents with separate columns for each dimensionality and vector indexes for ANN search.VECTOR INDEX statements create ANN indexes for each dimensionality.
import pymysqlimport jsonconn = pymysql.connect(host="127.0.0.1", port=3306, user="root")cursor = conn.cursor()cursor.execute("CREATE DATABASE IF NOT EXISTS matryoshka_demo")cursor.execute("USE matryoshka_demo")cursor.execute("""CREATE TABLE IF NOT EXISTS documents (id INT PRIMARY KEY AUTO_INCREMENT,text TEXT,embedding_64 VECTOR(64, F32) NOT NULL,embedding_128 VECTOR(128, F32) NOT NULL,embedding_256 VECTOR(256, F32) NOT NULL,embedding_512 VECTOR(512, F32) NOT NULL,embedding_768 VECTOR(768, F32) NOT NULL,VECTOR INDEX (embedding_64) INDEX_OPTIONS '{"metric_type":"DOT_PRODUCT"}',VECTOR INDEX (embedding_128) INDEX_OPTIONS '{"metric_type":"DOT_PRODUCT"}',VECTOR INDEX (embedding_256) INDEX_OPTIONS '{"metric_type":"DOT_PRODUCT"}',VECTOR INDEX (embedding_512) INDEX_OPTIONS '{"metric_type":"DOT_PRODUCT"}',VECTOR INDEX (embedding_768) INDEX_OPTIONS '{"metric_type":"DOT_PRODUCT"}')""")conn.commit()
For more information about vector indexing, refer to Vector Indexing.
Insert Documents
Insert each document and its embeddings into the documents table.
cols = ["text"] + [f"embedding_{dim}" for dim in DIMENSIONS]placeholders = ", ".join(["%s"] * len(cols))batch_data = []for text in documents:embeddings = generate_document_embedding(text, DIMENSIONS)batch_data.append([text] + [json.dumps(embeddings[dim]) for dim in DIMENSIONS])cursor.executemany(f"INSERT INTO documents ({', '.join(cols)}) VALUES ({placeholders})",batch_data)conn.commit()
Search at a Specific Dimensionality
Search using the 256-dimensional embeddings as an example:
query_embeddings = generate_query_embedding("What are the Bennet family's financial concerns?",DIMENSIONS)cursor.execute("""SELECT id, text,DOT_PRODUCT(embedding_256, %s :> VECTOR(256)) AS scoreFROM documentsORDER BY score DESCLIMIT 5""", (json.dumps(query_embeddings[256]),))results = cursor.fetchall()for i, (doc_id, text, score) in enumerate(results[:3], 1):preview = text[:60] + "..." if len(text) > 60 else textprint(f" {i}. {preview}")
Example Search Results
Semantic queries are run against the Pride and Prejudice dataset using 64, 128, 256, 512, and 768 dimensions.
For example:
Query: "What are the Bennet family's financial concerns?"
|
Dimensions |
Top-5 overlap with 768d |
|---|---|
|
64d |
40% |
|
128d |
40% |
|
256d |
60% |
|
512d |
80% |
|
768d |
100% (baseline) |
The overlap measures how many of the top-five results from each dimensionality are also returned by the 768-dimensional baseline.
Note: Individual query results may vary with small datasets.
Choosing a Prefix Length
The example demonstrates the trade-off between dimensionality and retrieval quality.
Storage Considerations
This example stores all five dimensionalities in separate columns to demonstrate the trade-offs at each dimension.
If you are cost-constrained in production, you can store only a smaller dimension (e.
Limitations
Matryoshka truncation depends on the embedding model being trained to preserve useful information in earlier dimensions.
Lower-dimensional prefixes generally retain less information than the full embedding, so shorter prefixes may reduce accuracy.
In this example, the Nomic Embed v1.
Related Topics
Last modified: